Variants of uncertain significance (VUS) are routinely reclassified as evidence accumulates, yet whether such reclassification can be anticipated from the evidence available while a variant is still uncertain is rarely evaluated directly. Longitudinal variant evaluations typically score static pathogenic-versus-benign discrimination on newly labelled variants, rather than the uncertain-to-resolved transition itself. We present ReVUS, a benchmark that labels every variant classified as a VUS in a fixed ClinVar release by its observed germline reclassification in a strictly later release, making it contamination-resistant by a temporal-holdout construction. The dataset comprises 580,386 VUS from the 2022-06 release scored against the 2026-07 release, of which 23,677 (4.1%) resolved to a definite pathogenic or benign call. ReVUS defines two tasks: predicting the direction of resolution among variants that resolve, and predicting whether a variant will resolve toward pathogenic. It standardises on imbalance-aware metrics and reports reference baselines, including variant-effect predictors evaluated with an explicit distinction between methods that depend on ClinVar labels and methods independent of them. Trained baselines show both tasks are learnable and that most of the signal on the whole-corpus task is gene-level: predicting resolution toward pathogenic reaches a 10.9× lift under a random split but only 2.0× once genes are held out, so resolution reflects substantial gene-level effects, including curation attention and gene-specific prior biology, that a gene-disjoint split separates from the variant-level signal. The contribution is the evaluation artifact and this analysis rather than a new predictive method. The benchmark, its deterministic build, and the baselines are openly available.
Clinical interpretation places each human genetic variant on a five-tier scale, from benign through uncertain to pathogenic, following the ACMG/AMP framework [1]. A large and growing share of interpreted variants fall in the middle tier: variants of uncertain significance (VUS), for which the available evidence supports neither a benign nor a pathogenic call. A VUS is not a permanent state. As new evidence accrues, such as additional cases, functional assays, population data, and expert-panel curation, a variant may be reclassified toward pathogenic or toward benign, or it may remain uncertain. This reclassification is clinically consequential: a variant that moves from uncertain to pathogenic can change surveillance, treatment, or reproductive decisions, and the reverse move can retire an unnecessary concern.
Anticipating which VUS will be reclassified, and in which direction, is therefore a task of direct clinical value, and one that computational methods might help prioritise. Yet, to our knowledge, no standard benchmark targets it directly. Longitudinal evaluations of variant-effect predictors typically measure static discrimination, meaning how well a score separates pathogenic from benign variants, on sets of variants that were newly classified after a predictor was published, as a guard against training-data circularity [2, 3]. That design answers a different question from the one clinicians face with a VUS in hand. It scores a method on variants that already carry a definite label; it does not ask whether a method can, from information available while a variant is still uncertain, anticipate the direction the eventual reclassification will take.
We introduce ReVUS, a benchmark built directly around that transition. Using the public archive of dated ClinVar releases [4], we take every variant classified as a VUS at a fixed freeze release and label it by its observed germline classification at a strictly later release. The label is thus the realised reclassification of a variant that was uncertain at freeze time. Because a method may use only information available at the freeze date, and the outcome is drawn from a later release, the benchmark is contamination-resistant by construction, the temporal analogue of the holdout designs used to guard variant-effect predictors against evaluation circularity [2]. ReVUS defines two tasks: among the variants that resolve, predicting whether the resolution is toward pathogenic or toward benign; and, over the full set of uncertain variants, predicting whether a variant will resolve toward pathogenic. Because the resolving and pathogenic classes are rare, it standardises on imbalance-aware metrics rather than raw accuracy. As reference points it reports two kinds of baseline: single-feature rankers, which order variants by one score, and trained models, which combine several and are evaluated under a gene-disjoint split, so that a method earns credit for judging the individual variant rather than for recognising which genes tend to be re-curated. Each baseline is labelled by whether it depends on ClinVar’s own labels or is independent of them.
The relevant provenance axis for a method is not publication date but outcome independence: whether a method’s scores depend on ClinVar classifications at all. The temporal holdout guarantees that no method can have observed the 2022–2026 reclassification events themselves; a predictor such as REVEL, published in 2016, plainly could not have. What a ClinVar-trained predictor can instead inherit is the label-generating process: the genes, submitting laboratories, and ascertainment conventions that produced its training labels are the same ones that produce ClinVar’s later classifications. This is the gene- and protein-level (“type-2”) circularity described by Grimm et al. [2]. ReVUS is built to make this axis visible rather than to remove it: it requires each method to declare whether it depends on ClinVar labels and reports ClinVar-dependent and ClinVar-independent methods side by side.
Reclassification of uncertain variants has been characterised before. Laboratory-cohort and single-release studies have reported reclassification rates, directions, and time courses in hereditary-cancer and other panels [5, 6]. To our knowledge, however, no prior work releases a variant-level labelled corpus of the uncertain-to-resolved transition with fixed tasks, imbalance-aware metrics, and a provenance-declared reference comparison; that packaged, reusable artifact is the contribution here, rather than a new predictive method. Section 2 describes the dataset and its construction, Section 3 defines the tasks and metrics, and Section 4 reports the reference baselines.
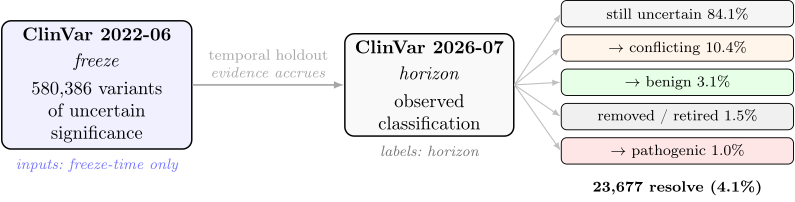
ReVUS is built by differencing two dated ClinVar releases (Figure 1). From the freeze release (2022-06) we take every variant whose aggregate germline classification is “uncertain significance” on the GRCh38 assembly. Each such variant is then looked up in the horizon release (2026-07) and labelled by the transition its germline classification underwent: to pathogenic (pathogenic or likely-pathogenic), to benign (benign or likely-benign), to conflicting, still VUS, or removed when the variant is no longer present in the later release. The label construction is a deterministic function of the two public releases and uses no external data or services; the build script and the exact release dates are distributed with the benchmark. The predictor features that accompany the resolved variants are a separate artifact: a frozen extract from a pinned BioBTree [7] snapshot (v2.10.0), not itself a function of the two ClinVar releases; the shipped gnomad_af is the global gnomAD allele frequency, or the grpmax (popmax) value where the global figure is absent. Every variant is keyed by its ClinVar VariationID, which is stable across releases and serves as the join key for external annotations.
The freeze release contributes 580,386 VUS. Their observed outcomes at the horizon are summarised in Table 1. The great majority remain uncertain; 23,677 (4.1%) resolve to a definite pathogenic or benign call, and resolution is imbalanced (benign outcomes outnumber pathogenic by roughly three to one), so the benchmark is scored with imbalance-aware metrics (Section 3).
| Outcome | Variants | Share |
| Still uncertain | 487,967 | 84.1% |
| → conflicting | 60,116 | 10.4% |
| → benign / likely-benign | 18,161 | 3.1% |
| Removed / retired | 8,559 | 1.5% |
| → pathogenic / likely-pathogenic | 5,516 | 1.0% |
| Other (risk-factor / association) | 67 | < 0.1% |
| Resolved to a definite call | 23,677 | 4.1% |
| Total | 580,386 | — |
Outcomes are not uniform across the corpus, so the benchmark reports them by subgroup as well as in aggregate. Variant type has the strongest effect on the direction of resolution (Table 2): among single-nucleotide variants that resolve, only 19.6% move toward pathogenic, whereas among resolving deletions 67.7% do. A method that ignores variant type will therefore be wrong for some types, so the direction task is reported per type as well as in aggregate.
| Variant type | VUS at freeze | Resolved | % pathogenic |
| Single-nucleotide variant | 543,968 | 21,468 | 19.6% |
| Deletion | 13,541 | 1,219 | 67.7% |
| Duplication | 7,157 | 433 | 62.1% |
| Microsatellite | 6,094 | 363 | 37.7% |
| Indel | 3,676 | 82 | 63.4% |
Resolution also varies with the review status a variant held at the freeze, but not as a simple gradient, and partly for a mechanical reason. Expert-panel variants resolve most often and multiple-concordant-submitter variants least (Table 3), yet much of that gap is an artefact of how ClinVar combines submissions rather than a difference in evidence quality: concordant multi-submitter variants often move sideways into conflicting (which we do not count as resolved), while an expert-panel record cannot become conflicting at all, which inflates its apparent resolution rate. The trend is real but should be read with that in mind, and because it is non-monotonic, review status on its own does not cleanly predict which variants will resolve.
| Freeze review status | Variants | Resolved |
| Reviewed by expert panel | 1,036 | 12.6% |
| No assertion criteria provided | 15,997 | 5.8% |
| Criteria provided, single submitter | 488,150 | 4.5% |
| Criteria provided, multiple submitters, no conflicts | 75,203 | 0.6% |
Finally, the removed / retired bin is mixed: some records were genuinely withdrawn, but others were merged into a new identifier after allele normalisation and may in fact have resolved under it. The current build does not follow these merges, so it counts the bin as a non-resolution and flags it as a source of label noise to tighten in a later version.
ReVUS defines two prediction tasks over the freeze-time VUS set. Both span variants of every type; only the sequence-predictor comparison (Table 4) is restricted to the missense subset, because those predictors are defined only for missense variants.
Task 1: resolution direction (conditional). Restricted to the 23,677 variants that resolved to a definite call, predict whether the resolution was toward pathogenic/likely-pathogenic or toward benign/likely-benign. This task conditions on a variable not known at deployment, namely whether the variant will resolve at all, so it measures a method’s ability to order variants by eventual direction and is intended for method comparison, not as an estimate of deployment performance. The set of variants that resolve is itself selected: resolved variants are enriched for well-studied genes and recurrent alleles, and the roughly 1:3.3 pathogenic-to-benign ratio is a property of what gets resolved rather than of the uncertain population. A missense subset is provided for sequence-based variant-effect predictors, which score amino-acid substitutions only. (The shipped predictor-feature table covers all 23,677 resolved variants; 44 carry no predictor value at all (absent from gnomAD, conservation, and SaProt alike) and are shipped with empty feature columns rather than dropped. Per-predictor coverage varies (SaProt 6,573, phyloP 23,572, gnomAD 17,361), which the tables report as each row’s n.)
Task 2: resolution toward pathogenic. Over the full 580,386-variant set, predict whether a freeze-time VUS will resolve toward pathogenic (≈ 1% positive). Unlike Task 1, this conditions on nothing known only in hindsight, so it is the quantity a triage system would actually optimise: which uncertain variants are heading toward a pathogenic call. It is the recommended headline endpoint. The benchmark ships no sequence or predictor features for the full corpus, so methods addressing this task supply their own annotations; the reference baselines here use only freeze-time metadata.
Split. Both tasks use the temporal holdout: inputs are restricted to information available at the freeze release, and labels are taken from the strictly later horizon release. This is a simulated-prospective evaluation; a truly prospective variant, in which predictions are registered against today’s VUS and scored as they resolve in future releases, is discussed in Section 5 as a planned extension. For the whole-corpus task (Task 2) the primary cross-validation protocol is additionally gene-disjoint: no gene appears in both the training and the evaluation folds. A random split lets a model memorise which genes are re-curated and which yield pathogenic calls, so it can be won by gene identity rather than variant-level signal; the gene-disjoint split removes that route and isolates the generalisable signal. We report the random split alongside it because the gap between the two is itself a result (Section 4).
Metrics. Both tasks are class-imbalanced (roughly 1:3.3 pathogenic-to-benign in Task 1, and 1% positive in Task 2). Under such imbalance raw accuracy is misleading, because always predicting the majority class scores well while learning nothing, so we report two rank-based measures instead. The primary measure is the area under the precision–recall curve (AUPRC), which is high only when a method ranks the rare positives above the negatives. Alongside it we quote ROC-AUC (the area under the receiver–operating–characteristic curve), a second and more familiar rank-based summary; both are threshold-free. AUPRC has no fixed chance level: a random ranking scores the base rate, the fraction of examples that are positive. We therefore report the base rate and a majority-class floor beside every AUPRC, summarise performance as lift (AUPRC divided by the base rate, the factor above chance), and do not compare AUPRC values across sets with different base rates. AUPRC is reported with a 95% confidence interval obtained by bootstrap resampling over variants; ROC-AUC is a point estimate. The repository additionally reports balanced accuracy (the mean of the true-positive and true-negative rates) at each method’s conventional threshold. Because outcomes vary by variant type and review status, headline results are also reported for those subgroups. Finally, any method evaluated on the benchmark must declare whether it depends on ClinVar labels, since a ClinVar-dependent score evaluated against a ClinVar-derived target is subject to a circularity the benchmark is designed to make visible.
We report reference baselines for both tasks, using off-the-shelf predictors and trained models, each labelled by whether it depends on ClinVar labels, to characterise how hard each task is and to establish the evaluation protocol.
For the direction task (Task 1) we score established sequence-based variant-effect predictors on the missense subset of resolved variants, discriminating variants that resolved toward pathogenic from those that resolved toward benign, on the 6,560 variants for which AlphaMissense [8], REVEL [9], and SaProt [10] are all defined (base rate toward pathogenic = 0.38); each predictor carries an explicit label for whether it was trained on ClinVar classifications. Table 4 reports the comparison. The ClinVar-trained REVEL leads (AUPRC 0.899); the ClinVar-independent AlphaMissense (0.872) and SaProt (0.850) follow, their confidence intervals separated from REVEL’s but by a modest margin (≈ 0.03). The trivial ClinVar-independent gnomAD-rarity ranking reaches 0.745, close to the sequence predictors, while sequence conservation (phyloP) is weak on this set (0.537); all clear the majority-class floor (0.382). Because AUPRC has no fixed chance level we report the base rate and floor alongside and do not compare AUPRC across sets with different base rates: gnomAD rarity scored only on the gnomAD-present variants within this matched set falls to 0.40 at base rate 0.21, and phyloP reaches 0.53 on its broader 23,572-variant coverage at base rate 0.23, both base-rate effects rather than genuine gains.
| Predictor | ClinVar-trained | n | base | AUPRC (95% CI) | ROC-AUC |
| REVEL | yes | 6,560 | 0.38 | 0.899 (0.887–0.911) | 0.935 |
| AlphaMissense | no | 6,560 | 0.38 | 0.872 (0.861–0.886) | 0.921 |
| SaProt | no | 6,560 | 0.38 | 0.850 (0.835–0.864) | 0.893 |
| gnomAD rarity | no | 6,560 | 0.38 | 0.745 (0.728–0.761) | 0.838 |
| Conservation (phyloP) | no | 6,555 | 0.38 | 0.537 (0.518–0.559) | 0.713 |
| Majority (benign) | — | 6,560 | 0.38 | 0.382 | 0.500 |
To test whether the tasks are learnable, and how much of any signal is variant-level rather than an artifact of which genes attract curation, we fit a gradient-boosting model with five-fold cross-validation (scoring out-of-fold predictions) and evaluate it under a random split and a gene-disjoint split (Table 5). For Task 1 the features are the ClinVar-independent scores (SaProt, conservation, gnomAD frequency) together with freeze-time metadata; for Task 2, over the full corpus for which the benchmark ships no predictor features, they are metadata only (variant type, review status, submitter count, chromosome, and the gene’s freeze-time VUS count).
On Task 1 the trained model reaches AUPRC 0.898 under the gene-disjoint split, close to the ClinVar-trained REVEL (0.899) and above AlphaMissense (0.872), though the two are evaluated on slightly different sets (n = 6,573 vs 6,560) and by different protocols (cross-validated versus off-the-shelf). This gene-disjoint value is close to the random-split value (0.931), a small gap. On Task 2 the model clears its ≈ 1% base rate by a wide margin under a random split (lift 10.9×) but falls back sharply under the gene-disjoint split (lift 2.0×); the same drop appears for the coarser question of whether a variant resolves at all (3.0× to 1.4×).
| Task | Split | base | AUPRC (95% CI) | lift | ROC-AUC |
| 1 (direction) | gene-disjoint | 0.38 | 0.898 (0.887–0.909) | 2.35× | 0.931 |
| 1 (direction) | random | 0.38 | 0.931 (0.920–0.941) | 2.43× | 0.957 |
| 2 (toward pathogenic) | gene-disjoint | 0.010 | 0.019 (0.018–0.020) | 1.98× | 0.633 |
| 2 (toward pathogenic) | random | 0.010 | 0.104 (0.096–0.112) | 10.9× | 0.811 |
The intervals in Table 5 bootstrap over variants at a fixed fold assignment, so they capture evaluation-set sampling but not cross-validation variability and are narrower than a fully-resampled interval would be; the gene partition is a single GroupKFold split, not averaged over partitions. The reference implementation pins its dependency versions so the numbers reproduce exactly.
ReVUS turns the reclassification transition itself into a prediction target: by labelling freeze-time VUS with their observed reclassification at a later ClinVar release, it asks whether the eventual outcome can be anticipated from the evidence available while a variant is still uncertain, and its temporal-holdout construction makes it contamination-resistant by design.
The clearest result from the reference baselines is that the two tasks fall on opposite sides of the gene-disjoint split. Predicting the direction of resolution barely changes when genes are held out (AUPRC 0.931 under a random split, 0.898 gene-disjoint), so which way a resolving variant moves is largely a property of the variant itself. Predicting resolution over the whole corpus does the reverse: a metadata-only model reaches 10.9× lift under a random split but only 2.0× once genes are held out, and the same collapse appears for whether a variant resolves at all. Whether a variant resolves is therefore mostly a property of its gene, while the direction it resolves in is a property of the variant. The gene-disjoint protocol is what separates the two, which is why it is the benchmark’s primary setting: it measures what a method can learn about variants that generalises to unseen genes, and the gap between the two splits is itself the quantity of interest.
This bears on both the biology and the evaluation. Which variants are re-curated toward a pathogenic call is shaped largely by which genes attract attention: curation concentrates on established disease genes, high-throughput-assayed loci, and genes of clinical interest, and those genes carry stronger priors toward pathogenic outcomes, so a model can score well on a random split by recognising gene identity alone. A method meant to generalise should therefore be evaluated under a gene-disjoint split and built to separate gene-level context from variant-level evidence rather than to exploit their correlation; a random-split number alone would overstate how much it has learned about the variant itself.
A second axis worth separating is provenance: what matters is outcome independence, not publication date. The temporal holdout guarantees that no method observed the 2022–2026 reclassification events, so the relevant question is whether a method’s scores derive from ClinVar classifications at all. AlphaMissense and SaProt postdate the freeze but were not trained on ClinVar labels, so their scores are outcome-independent; a ClinVar-trained predictor such as REVEL can instead inherit the label-generating process behind ClinVar’s later classifications, the gene-level circularity described by Grimm et al. [2]. Reporting the two provenance classes side by side keeps this visible: REVEL’s small edge over AlphaMissense on the direction task is equally consistent with its being a stronger classifier as with residual circularity, and once independent features are combined a trained model matches it. Because REVEL enters without a training fold, the gene-disjoint split cannot settle its circularity directly.
Several properties should be read alongside any result on the benchmark. The labels are ClinVar aggregate germline classifications and inherit ClinVar’s submission composition and review conventions; a change in the horizon classification reflects the accumulation of submitted evidence, not an independent gold standard. The evaluation is simulated-prospective rather than truly prospective: the freeze and horizon are both historical, and although a method may use only freeze-time inputs, the outcomes were already realised when the benchmark was assembled. Task 1 additionally conditions on resolution, a variable not known at deployment, so the variants that resolve are a selected subset, enriched for well-studied genes, high-throughput-assayed loci, and recurrent or founder alleles, and their pathogenic-to-benign ratio reflects what gets resolved rather than the composition of the uncertain population; Task 2 (over the full set) avoids this conditioning. Finally, the sequence-based predictors apply only to the missense subset, and non-coding, structural, and mitochondrial VUS require features other than amino-acid-level scores, which the benchmark reports by subgroup rather than folding into a single number.
The natural next version is a truly prospective, living benchmark: predictions are registered against the current set of VUS and scored automatically as subsequent ClinVar releases resolve them, which removes the residual concern that a historical outcome could influence method design and turns the benchmark into a continuously updating resource. Additional freeze–horizon windows (for example, an earlier freeze scored against the present) would characterise the stability of the task over time, and extending the shipped feature set beyond missense predictors to non-coding, structural, and mitochondrial variants would broaden the reference comparison to the full corpus.
The ReVUS benchmark is available at https://github.com/tamerh/ReVUS and https://sugi.bio/revus under the MIT license. It comprises the labelled dataset, the deterministic build script that reproduces it from public ClinVar releases, the shipped predictor features, the reference-baseline implementation, and the evaluation metrics. The labels and GRCh38 coordinates are derived from NCBI ClinVar, which is in the public domain. The shipped feature table includes only the predictor scores that permit redistribution (SaProt, phyloP conservation, and gnomAD allele frequency); AlphaMissense and REVEL are not, so the repository documents how to obtain them from dbNSFP and join them by ClinVar VariationID. The evaluation code accordingly reproduces the ClinVar-independent rows of Table 4 directly and the AlphaMissense and REVEL rows once those columns are added.
S. Richards et al. “Standards and guidelines for the interpretation of sequence variants: a joint consensus recommendation of the American College of Medical Genetics and Genomics and the Association for Molecular Pathology”. In: Genetics in Medicine 17.5 (2015), pp. 405–424. doi: 10.1038/gim.2015.30.
D. G. Grimm et al. “The evaluation of tools used to predict the impact of missense variants is hindered by two types of circularity”. In: Human Mutation 36.5 (2015), pp. 513–523. doi: 10.1002/humu.22768.
X. Liu, C. Li, C. Mou, Y. Dong, and Y. Tu. “dbNSFP v4: a comprehensive database of transcript-specific functional predictions and annotations for human nonsynonymous and splice-site SNVs”. In: Genome Medicine 12.1 (2020), p. 103. doi: 10.1186/s13073-020-00803-9.
M. J. Landrum et al. “ClinVar: improving access to variant interpretations and supporting evidence”. In: Nucleic Acids Research 46.D1 (2018), pp. D1062–D1067. doi: 10.1093/nar/gkx1153.
J. Mersch, N. Brown, S. Pirzadeh-Miller, E. Mundt, H. C. Cox, K. Brown, M. Aston, L. Esterling, S. Manley, and T. Ross. “Prevalence of Variant Reclassification Following Hereditary Cancer Genetic Testing”. In: JAMA 320.12 (2018), pp. 1266–1274. doi: 10.1001/jama.2018.13152.
S. M. Harrison, J. S. Dolinsky, A. E. Knight Johnson, T. Pesaran, D. R. Azzariti, S. Bale, S. Chen, A. J. Coffey, R. Colombo, S. K. Cordovado, et al. “Clinical laboratories collaborate to resolve differences in variant interpretations submitted to ClinVar”. In: Genetics in Medicine 19.10 (2017), pp. 1096–1104. doi: 10.1038/gim.2017.14.
T. Gür. BioBTree v2: Grounding LLM Responses with Large-Scale Structured Biomedical Data. 2026. doi: 10.5281/zenodo.18962899.
J. Cheng et al. “Accurate proteome-wide missense variant effect prediction with AlphaMissense”. In: Science 381.6664 (2023), eadg7492. doi: 10.1126/science.adg7492.
N. M. Ioannidis et al. “REVEL: An Ensemble Method for Predicting the Pathogenicity of Rare Missense Variants”. In: The American Journal of Human Genetics 99.4 (2016), pp. 877–885. doi: 10.1016/j.ajhg.2016.08.016.
J. Su, C. Han, Y. Zhou, J. Shan, X. Zhou, and F. Yuan. “SaProt: Protein Language Modeling with Structure-aware Vocabulary”. In: The Twelfth International Conference on Learning Representations (ICLR). 2024.