Method
The preprint behind the system. · Download PDF
Sugi Variant: A Deterministic Per-Variant Germline Reference from a Knowledge Graph for Humans and AI Agents
Abstract
Interpreting a germline genetic variant means assembling evidence that lives in many different places: its clinical classification and condition in one database, its population frequency in another, computational predictions in several more, and the formal evidence criteria an expert panel applied in yet another. Each resource is authoritative within its domain, yet a connected, current per-variant picture takes manual effort and goes stale as the sources update on their own cycles. This content is increasingly consumed by AI agents as well as people, raising the bar on how correct and current it must be. We present Sugi Variant, an openly published per-variant reference for germline human variants built by deterministically mining the BioBTree knowledge graph. It issues fixed chained-query plans, so every variant is assembled the same way on each run, each value straight from the source, and the reference is reproducible for a given snapshot. For each variant it consolidates the ClinVar germline classification and condition, the gnomAD allele frequency and gene constraint, calibrated predictors of variant effect (AlphaMissense, REVEL, a structure-aware protein language model, and sequence conservation), and the ClinGen ACMG/AMP criteria where an expert panel recorded them. One calibrated predictor carries evidence weight and the rest are read as agreement signals; an explicit concordance readout flags, as a signal for review rather than a reclassification, the variants where the computational evidence disagrees with the clinical classification, drawing attention where it is needed. The reference describes and aggregates existing evidence and never computes a classification of its own. It comprises 3,961,230 variants across 18,799 genes, including non-coding and mitochondrial variants, and is openly available at https://sugi.bio/variant/.
1 Introduction
Interpreting a human genetic variant means assembling evidence that is scattered across many separate resources. Its clinical classification and the conditions it is asserted for sit in one database, its population frequency in another, computational predictions of its effect in several more, and the formal evidence criteria a variant curation expert panel (VCEP) applied in yet another. Each resource is authoritative within its own domain, yet a clinician or researcher assessing a single variant must visit and reconcile them by hand, and because each is updated on its own cycle, any consolidated view begins to go stale the moment it is written down. Assembling a connected and current per-variant picture is therefore a recurring effort. This content is increasingly read by machines as well as people: large language models (LLMs) and autonomous agents now consume genomic reference data directly [1]. As additional consumers they raise the same properties a human reader needs, correctness and currency, more sharply, because an LLM asked to produce variant facts from memory fabricates plausible but unsupported statements, most often for the rare, sparsely-documented variants that dominate the long tail [2, 3]. Grounding an LLM against authoritative records mitigates this [4], but letting an LLM traverse a large graph does not yield a catalog: the traversal varies between runs and models, so coverage is neither complete nor reproducible, and the per-variant cost makes rebuilding on every data refresh impractical.
Several lines of work consolidate variant evidence so that it need not be gathered by hand each time. ClinVar aggregates clinical assertions and their supporting conditions [5]; gnomAD provides population allele frequencies and gene constraint [6]; dbNSFP precomputes and packages many computational predictors for missense variants [7]; and interpretation platforms and multi-source aggregators assemble several of these behind a query interface. These resources resolve much of the fragmentation. A complementary reference layer built on an integrated graph can add to them: one that spans variant classes, including the uncertain, non-coding, and mitochondrial variants often omitted; that is deterministic, and therefore reproducible and inexpensive to refresh; and that presents each variant’s clinical, population, and computational evidence together with an explicit readout of whether those independent lines of evidence agree, in one openly published place.
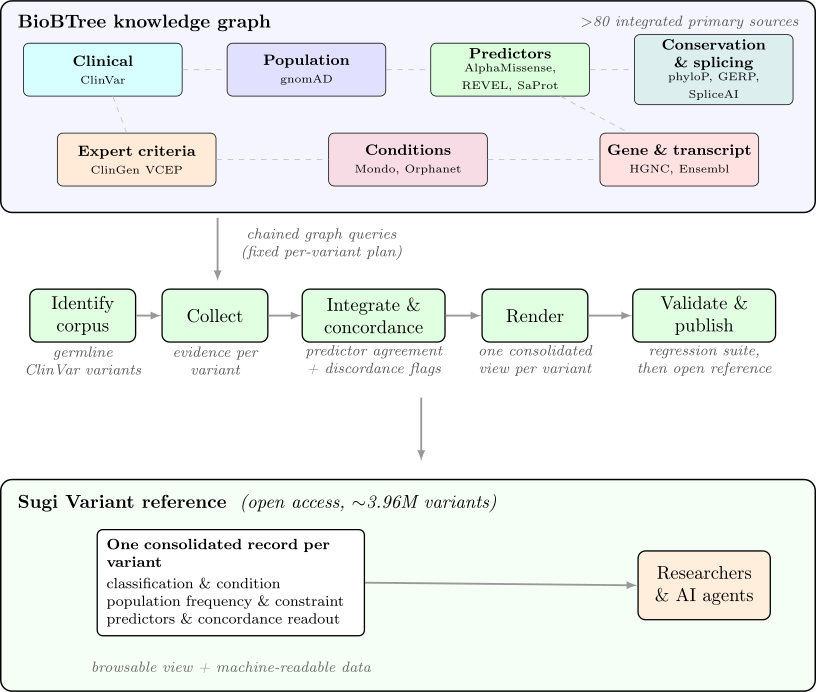
We present Sugi Variant, an openly published, per-variant reference for germline human variants produced by deterministically mining the BioBTree knowledge graph [8], which integrates more than eighty primary sources and stays current as those sources release updates. For each variant, a pipeline issues fixed chained graph queries that assemble, every value traced to its source, the ClinVar germline classification and asserted condition, the gnomAD allele frequency and gene constraint, calibrated computational predictors (AlphaMissense, REVEL, SaProt, conservation, and, for splice-region variants, SpliceAI), the ClinGen ACMG/AMP evidence criteria where an expert panel has recorded them, and a cross-source concordance readout that states whether the computational predictors agree with the clinical classification and flags the cases where they do not. Throughout, the reference describes and aggregates the existing evidence and never computes a classification of its own: the concordance readout is a quality-control signal for review, not a reclassification. Surfacing that disagreement as a visible signal, rather than resolving it into a new call, is a key part of the reference’s value: it directs a reviewer to the variants where clinical and computational evidence part ways. Because the reference is a deterministic function of BioBTree’s contents, every variant is presented at uniform breadth and, for a given snapshot, the reference is reproducible and stays current as the sources are re-ingested. Sugi Variant comprises 3,961,230 variants across 18,799 genes, spanning pathogenic and likely-pathogenic, conflicting, uncertain-significance, and benign classifications, and including non-coding and mitochondrial variants. Section 2 details the mining pipeline, Section 3 presents example variant views and the breadth of evidence they carry, and Figure 1 shows the overall design.
2 Methods
Sugi Variant is built on the BioBTree knowledge graph [8], consuming it through its API. It traverses the graph by chain queries, which follow cross-reference links from a starting record through a sequence of datasets and return the records reached. Each variant view is assembled by issuing the same fixed plan of such queries from one resolved variant, so every variant is assembled the same way on each build, coverage is uniform across the corpus, and, for a given BioBTree snapshot, the build is reproducible. The pipeline (Figure 1) identifies the corpus, collects each variant’s evidence, integrates it and assesses cross-source concordance, renders each variant’s view, and validates the result before publication; the following subsections describe these phases in turn.
2.1 Identify corpus
Sugi Variant covers germline human variants that carry a ClinVar clinical classification. ClinVar records several distinct classifications for a variant, and some variants carry, in addition to a germline classification, a somatic clinical-impact or oncogenicity classification asserted for tumours; Sugi Variant reads only the germline classification and its asserted condition, so a variant that carries only a somatic classification is not included: those somatic classifications sit on a different axis, graded for oncogenicity or clinical-impact tier rather than germline pathogenicity, and rest on evidence the germline-calibrated concordance readout would not interpret in the same terms. The corpus is enumerated per gene: for each gene, the pipeline lists its ClinVar variants through the graph and admits those carrying any of ClinVar’s germline classification categories, from pathogenic through uncertain and conflicting to benign (Table 1). This enumeration is not restricted to protein-coding missense variants: non-coding RNA and mitochondrial variants are admitted on the same basis wherever they carry a germline classification.
Together these admit 3,961,230 variants across 18,799 genes (Table 1), the majority of uncertain significance. Of the full corpus, 1,526 are non-coding-RNA variants (named in the non-coding n. form of HGVS, the sequence-variant nomenclature) and 3,077 are mitochondrial (m.) variants, classes many per-protein resources omit.
| Germline classification | Variants | Share |
| Pathogenic / Likely pathogenic | 312,788 | 7.9% |
| Conflicting | 154,083 | 3.9% |
| Uncertain significance | 2,236,650 | 56.5% |
| Benign / Likely benign | 1,257,709 | 31.8% |
| Total | 3,961,230 | – |
2.2 Collect content
Each admitted variant is first resolved to a single canonical ClinVar record, the anchor, which every section of its view then shares. From this anchor, a fixed plan of chain queries assembles the variant’s evidence (Figure 2), each value read directly from its source dataset rather than reconstructed: from ClinVar, the germline classification, the review status and submitter count, and the asserted condition, carried through to its Mondo [9] and Orphanet [10] terms; from gnomAD, the global allele frequency, the grouped-population maximum (grpmax), and the gene-level constraint (such as LOEUF and pLI); and, for the amino-acid change, the computational predictors AlphaMissense [11], REVEL [12], and SaProt [13], together with sequence conservation [14, 15] and, for splice-region variants, SpliceAI [16]. Where ClinGen variant curation expert panels (VCEPs) [17] have recorded a curation, the ACMG/AMP evidence criteria they applied are collected verbatim. A variant that resolves to nothing is recorded and skipped rather than aborting the build.
The evidence types differ in how many variants they apply to (Table 2, on a representative random sample). Position-based conservation reaches almost every variant; the missense predictors, scoring only amino-acid substitutions, reach about half; a gnomAD allele frequency is present only for variants observed in that database, absent for the many ClinVar variants that are private or novel alleles; and the ClinGen ACMG/AMP criteria exist only for the small, expert-curated subset a panel has reviewed. This unevenness is intrinsic to the evidence rather than a gap in the pipeline, and it is greatest on the uncertain, non-coding, and mitochondrial variants where the missense predictors fall silent.
| Evidence type | Coverage |
| ClinVar germline classification | 100% |
| Sequence conservation (phyloP, GERP) | 93.2% |
| REVEL | 61.6% |
| AlphaMissense | 58.9% |
| SaProt | 52.5% |
| gnomAD allele frequency (observed) | 47.6% |
| Asserted condition (Mondo term) | 46.7% |
| SpliceAI (splice-region, Δ ≥ 0.2) | 1.7% |
| ClinGen ACMG/AMP criteria | 0.6% |
2.3 Integrate evidence and assess concordance
The integration step assembles the collected evidence into a single readout and states whether its independent lines agree. Throughout, Sugi Variant follows the ClinGen Sequence Variant Interpretation framework [18] and describes the evidence rather than computing a classification of its own; the concordance readout is a quality-control signal for review, not a reclassification.
Because these predictors are not independent, the readout does not sum them. One calibrated predictor carries the evidence weight, AlphaMissense for a missense change and sequence conservation otherwise, and the rest are shown as agreement signals that concur or dissent, never as additive votes. SaProt, a structure-aware protein language model, is included because, unlike a ClinVar-trained ensemble such as REVEL, it does not learn from ClinVar labels, so its agreement is genuinely independent. Population rarity is shown for context but not counted as concordant evidence.
From these signals the view presents an explicit concordance readout and, where the independent lines disagree, labels the disagreement into a small set of quality-control categories, for example a pathogenic classification the calibrated predictor leans against, or a unanimous predictor lean on a variant of uncertain significance. These are surfaced as flags for review; none changes the recorded classification.
2.4 Render the variant view
Every variant is presented through the same canonical sequence of sections in a fixed order, each under a stable anchor identifier; a section for which no data resolves is shown as an explicit “no data” state rather than omitted, so that every variant has identical structure and a deep link to any section resolves for every variant. Beyond its sections, each view carries a one-sentence description and a short list of headline facts, both composed by template from the collected values. Every element is produced in this way, by deterministic composition from the record’s data; no part is generated by a language model. Each view is emitted as a Markdown document with a machine-readable metadata header and a schema.org record, so that programmatic consumers, including AI agents, read the same content it presents. To make each variant addressable by the identifiers people actually use, a resolution index maps its HGVS expressions, rsID (dbSNP identifier), genomic coordinate, and canonical slug to its ClinVar record, so that a query in any of these forms resolves to the same variant.
2.5 Validate and publish
Validation is layered, and begins upstream: BioBTree re-runs over a thousand test cases on every release to check the integrity of the underlying data and its cross-references [8]. On top of that, Sugi Variant is checked by a deterministic regression suite that samples variants stratified across variant type and classification, and, for each, verifies a set of invariants: that the variant view resolves and renders, that the displayed classification and review status match an independent query of the ClinVar summary service, that no missense predictor is shown for a variant type it does not score (for example, that a non-coding variant carries no protein constraint), and that a variant of uncertain or benign significance is described without pathogenic framing. The suite additionally carries a set of canonical variants whose facts are known independently of the pipeline, and a set of negative controls confirming that the checks fail on deliberately corrupted views, so that a passing run is evidence the checks have force rather than that nothing was tested. Because the reference is a deterministic function of BioBTree’s contents, it tracks the underlying databases as BioBTree re-ingests its sources, rather than following a manual release cycle.

3 Example variants
We illustrate the reference through four variants chosen to span its breadth and the concordance readout central to it: a variant on which every line of evidence agrees, one on which they do not, and two from classes many resources omit. Every variant follows the same contract; these are representative slices, not special cases.
3.1 A concordant variant: TP53 p.Arg175His
The view for the TP53 missense variant p.Arg175His opens with a deterministic lead composed from the collected fields, and its at-a-glance figures are read directly from the source: it is classified Pathogenic, reviewed by an expert panel (a three-star review status), and asserted for Li-Fraumeni syndrome, and it is very rare in the population (a gnomAD grouped-population maximum, grpmax, of 1.5 × 10⁻⁵). The computational evidence is presented as Section 2.3 prescribes: AlphaMissense, the calibrated missense predictor, calls the variant likely-pathogenic (0.986), and REVEL (0.922) and SaProt (a log-likelihood ratio of −15.6) are shown as concurring agreement signals rather than additional votes; all three lean damaging, concordant with the pathogenic classification. The view also carries, verbatim, the ACMG/AMP criteria the ClinGen TP53 expert panel applied (PM2_Supporting, PP1_Moderate, PS3, PS4_Moderate, PM1, and PP3). This is the common case: a well-studied variant on which clinical, population, and computational evidence agree, assembled in one place, and the concordance readout confirms the alignment and raises no flag.
3.2 A variant of uncertain significance with a discordance flag: PTEN p.Pro38Ser
The PTEN missense variant p.Pro38Ser is the case the concordance readout is built for. It is classified as of uncertain significance, and, as with the TP53 example, that classification is an expert-panel one: the ClinGen PTEN expert panel recorded it as uncertain, applying PM2_Supporting, PS3_Moderate, PP2, and PP3. The variant is absent from gnomAD. Yet all three computational predictors lean damaging: AlphaMissense (0.9998) and REVEL (0.957) strongly, and SaProt (log-likelihood ratio −10.3) only narrowly, just past its calibrated damaging threshold of −10.0, so its contribution to the unanimous lean is marginal. The view holds the recorded uncertain classification unchanged and surfaces this tension as a quality-control flag: the computational predictors unanimously lean damaging on a variant the clinical record leaves uncertain, a signal for review, not a reclassification. The view makes the disagreement visible in one place without overriding either line of evidence; Section 4 discusses why a panel may hold such a variant uncertain despite a unanimous predictor lean.
3.3 Variants outside the missense predictors’ scope: MT-TL1 m.3243A>G and RMRP n.72A>G
A large class of clinically important variants cannot be scored by the missense-predictor stack at all, and Sugi Variant carries them on the same contract rather than omitting them. The mitochondrial variant m.3243A>G in MT-TL1, classified Pathogenic by the ClinGen Mitochondrial Diseases expert panel and asserted for mitochondrial disease, lies in a mitochondrial transfer-RNA gene; its view presents the clinical and population evidence, the expert-panel criteria (PM6_Strong, PP1_Moderate, PS4, and PP3), and the mitochondrial mode of inheritance, with the missense predictors marked as inapplicable rather than left blank. The non-coding-RNA variant n.72A>G in RMRP, classified pathogenic/likely-pathogenic and asserted for anauxetic dysplasia, is similarly outside the predictors’ scope; its view presents classification, condition, and population frequency together with the conservation signal where it is available. Its grouped-population maximum (grpmax) of 1.4 × 10⁻³ understates its local frequency, since n.72A>G is a founder variant for cartilage-hair hypoplasia, reaching several per cent in the Amish and near one per cent in Finns, so the per-population values the view also carries matter more than the aggregate.
3.4 Grounding a language model with Sugi Variant
Because each record is emitted as machine-readable structured data, it can also serve as a grounding source for a language model answering a question about a variant, a setting in which a closed-book model is otherwise prone to fabricate plausible but unsupported facts, most often for the rare variants sparsely represented in its training data [2, 3], and in which grounding against authoritative records reduces such fabrication [4, 19]. In a small paired trial over two frontier Claude models (Sonnet and Opus), grounding with the record recovered variant facts a closed-book model essentially could not, and it matched a live web search on accuracy while returning the same facts on every run, in a single lookup at lower token cost (about a quarter less in our runs). Its value for grounding is thus determinism and cost rather than higher accuracy; we report it as an illustration, and leave a powered evaluation to future work.
4 Discussion
Sugi Variant mines BioBTree deterministically into a per-variant reference for germline human variants. Each variant view is assembled by issuing a fixed plan of chain queries and rendering the records they return, and the clinical, population, and computational evidence gathered along the way is presented together with an explicit readout of whether its independent lines agree. We took this deterministic route for what a reference most needs: each value is exactly what the source data records, every variant is presented at the same breadth, and, for a given BioBTree snapshot, the reference is reproducible and stays current as the sources are refreshed. The result, as the example variants illustrate, consolidates a variant’s scattered evidence in one place and states plainly whether that evidence is concordant.
A distinctive strength follows from a deliberate boundary: the reference describes and aggregates the evidence rather than reducing it to a new interpretation, so it makes disagreement visible instead of hiding it inside a single call. Following the ClinGen interpretation framework [18], it reads one calibrated predictor as carrying weight and the others as agreement signals rather than combining them into a single score, and the concordance readout it derives is a quality-control flag for review, never a computed classification. The PTEN p.Pro38Ser example shows why this matters: an expert panel held the variant at uncertain while every predictor leaned damaging, and the reference’s value is to put that disagreement in front of a reviewer, in one place, without overriding either line, guiding attention rather than issuing a verdict. Where evidence is simply absent, such as the missense predictors on a mitochondrial transfer-RNA or a non-coding-RNA variant, the view shows an honest empty rather than a missing field, and carries the variant on the same contract as any other.
Several established resources also consolidate variant evidence (ClinVar, gnomAD, dbNSFP, and interpretation platforms, as noted in Section 1); these are valuable and offer much that Sugi Variant does not. In turn, Sugi Variant’s principal contribution is a per-variant germline reference assembled deterministically from an integrated biomedical knowledge graph, and therefore reproducible and current. Its breadth across variant classes, the explicit cross-source concordance readout, and the machine-readable records follow from that design rather than standing as separate claims: one fixed traversal of one integrated graph is what lets the same broad, structured view be produced for every variant and regenerated as the sources change. Sugi Variant adds no new predictive signal; on these terms it is a complementary reference.
Because each record is machine-readable, the reference also serves as a grounding source for language-model question answering. In a paired pilot it matched a live web search on accuracy while adding determinism and lower token cost (Section 3.4), the properties a fixed reference, rather than a search, is meant to provide.
5 Limitations
Sugi Variant aggregates existing, largely public sources; its accuracy for any single value is therefore inherited from the source, and its contribution is integration, coverage, and reproducibility rather than new evidence about a variant. A few displayed quantities depend on Sugi Variant’s own aggregation conventions rather than on a source value alone, among them the allele-frequency denominator and the predictor display thresholds, and are documented with the pipeline. By design it does not resolve variants of uncertain significance: it surfaces the evidence and flags disagreement, but records the source classification unchanged, and the concordance flags are review signals whose calibration to clinical outcome we do not claim. Coverage is scoped to germline variants that carry a ClinVar germline classification; somatic clinical-impact and oncogenicity interpretations, and variants absent from ClinVar, are out of scope. For non-missense and non-coding variants the computational layer is necessarily thin, because the calibrated predictors score amino-acid substitutions only, so for those classes the view rests on clinical and population evidence and conservation where available. Finally, the grounding result is a small pilot on two models and a single run; it demonstrates the utility of the structured record as a grounding source but is not a powered evaluation, which we leave to future work.
6 Future work
Several directions would extend Sugi Variant. Because the reference is a deterministic function of BioBTree and inexpensive to rebuild, we plan to regenerate it on a regular cadence so that it tracks the underlying sources as they release updates. The grounding demonstration invites a powered evaluation of the reference as a grounding source for agentic variant question-answering, with the stratified, deterministic scoring the pilot prototypes. Separately, the temporal record of how classifications change over successive ClinVar releases supports a benchmark for variant reclassification, which we develop in a companion work [20]. Finally, the same deterministic mining can extend the per-variant contract with further curated evidence as it becomes available, within the same reproducible design.
7 Availability
Sugi Variant is openly available at https://sugi.bio/variant/, where every variant has a stable, browsable view. The build pipeline is open-source software released under the MIT license, and can be deployed locally. Sugi Variant is built on BioBTree [8], the knowledge graph it mines, and can be regenerated as that graph is refreshed.
- Sugi Variant pipeline (source and documentation): https://github.com/tamerh/sugi-variant
- Published reference: https://sugi.bio/variant/
- BioBTree: https://github.com/tamerh/biobtree
References
- [1]
-
K. Singhal, S. Azizi, T. Tu, S. S. Mahdavi, J. Wei, H. W. Chung, N. Scales, A. Tanwani, H. Cole-Lewis, S. Pfohl, et al. “Large language models encode clinical knowledge”. In: Nature 620.7972 (2023), pp. 172–180. doi: 10.1038/s41586-023-06291-2.
- [2]
-
M. Bhattacharyya, V. M. Miller, D. Bhattacharyya, and L. E. Miller. “High Rates of Fabricated and Inaccurate References in ChatGPT-Generated Medical Content”. In: Cureus 15.5 (2023), e39238. doi: 10.7759/cureus.39238.
- [3]
-
W. H. Walters and E. I. Wilder. “Fabrication and errors in the bibliographic citations generated by ChatGPT”. In: Scientific Reports 13 (2023), p. 14045. doi: 10.1038/s41598-023-41032-5.
- [4]
-
X. Hou, Y. Zhao, S. Wang, and H. Wang. Model Context Protocol (MCP): Landscape, Security Threats, and Future Research Directions. Mar. 2025. doi: 10.48550/arXiv.2503.23278.
- [5]
-
M. J. Landrum et al. “ClinVar: improving access to variant interpretations and supporting evidence”. In: Nucleic Acids Research 46.D1 (2018), pp. D1062–D1067. doi: 10.1093/nar/gkx1153.
- [6]
-
S. Chen et al. “A genomic mutational constraint map using variation in 76,156 human genomes”. In: Nature 625 (2024), pp. 92–100. doi: 10.1038/s41586-023-06045-0.
- [7]
-
X. Liu et al. “dbNSFP v4: a comprehensive database of transcript-specific functional predictions and annotations for human nonsynonymous and splice-site SNVs”. In: Genome Medicine 12 (2020), p. 103. doi: 10.1186/s13073-020-00803-9.
- [8]
-
T. Gür. BioBTree v2: Grounding LLM Responses with Large-Scale Structured Biomedical Data. 2026. doi: 10.5281/zenodo.18962899.
- [9]
-
N. A. Vasilevsky, N. A. Matentzoglu, S. Toro, J. E. Flack, H. Hegde, D. R. Unni, G. F. Alyea, J. S. Amberger, L. Babb, J. P. Balhoff, et al. “Mondo: Unifying diseases for the world, by the world”. In: medRxiv (2022). doi: 10.1101/2022.04.13.22273750.
- [10]
-
S. Maiella, A. Rath, C. Angin, F. Mousson, and O. Kremp. “Orphanet and its consortium: where to find expert-validated information on rare diseases”. In: Revue Neurologique 169 (2013), S3–S8. doi: 10.1016/S0035-3787(13)70060-3.
- [11]
-
J. Cheng et al. “Accurate proteome-wide missense variant effect prediction with AlphaMissense”. In: Science 381.6664 (2023), eadg7492. doi: 10.1126/science.adg7492.
- [12]
-
N. M. Ioannidis et al. “REVEL: An Ensemble Method for Predicting the Pathogenicity of Rare Missense Variants”. In: The American Journal of Human Genetics 99.4 (2016), pp. 877–885. doi: 10.1016/j.ajhg.2016.08.016.
- [13]
-
J. Su, C. Han, Y. Zhou, J. Shan, X. Zhou, and F. Yuan. “SaProt: Protein Language Modeling with Structure-aware Vocabulary”. In: The Twelfth International Conference on Learning Representations (ICLR). 2024.
- [14]
-
K. S. Pollard, M. J. Hubisz, K. R. Rosenbloom, and A. Siepel. “Detection of nonneutral substitution rates on mammalian phylogenies”. In: Genome Research 20.1 (2010), pp. 110–121. doi: 10.1101/gr.097857.109.
- [15]
-
E. V. Davydov, D. L. Goode, M. Sirota, G. M. Cooper, A. Sidow, and S. Batzoglou. “Identifying a High Fraction of the Human Genome to be under Selective Constraint Using GERP++”. In: PLoS Computational Biology 6.12 (2010), e1001025. doi: 10.1371/journal.pcbi.1001025.
- [16]
-
K. Jaganathan et al. “Predicting Splicing from Primary Sequence with Deep Learning”. In: Cell 176.3 (2019), pp. 535–548. doi: 10.1016/j.cell.2018.12.015.
- [17]
-
H. L. Rehm et al. “ClinGen — The Clinical Genome Resource”. In: New England Journal of Medicine 372.23 (2015), pp. 2235–2242. doi: 10.1056/NEJMsr1406261.
- [18]
-
V. Pejaver et al. “Calibration of computational tools for missense variant pathogenicity classification and ClinGen recommendations for PP3/BP4 criteria”. In: The American Journal of Human Genetics 109.12 (2022), pp. 2163–2177. doi: 10.1016/j.ajhg.2022.10.013.
- [19]
-
Q. Jin et al. “GeneGPT: augmenting large language models with domain tools for improved access to biomedical information”. In: Bioinformatics 40.2 (2024), btae075. doi: 10.1093/bioinformatics/btae075.
- [20]
-
T. Gür. ReVUS: A Temporal-Holdout Benchmark for the Reclassification of Variants of Uncertain Significance. https://sugi.bio/revus. 2026. doi: 10.5281/zenodo.21496351.